Next-Concept Modeling: Stanford Researchers Unveil Revolutionary AI Architecture to Overcome Autoregressive Limitations

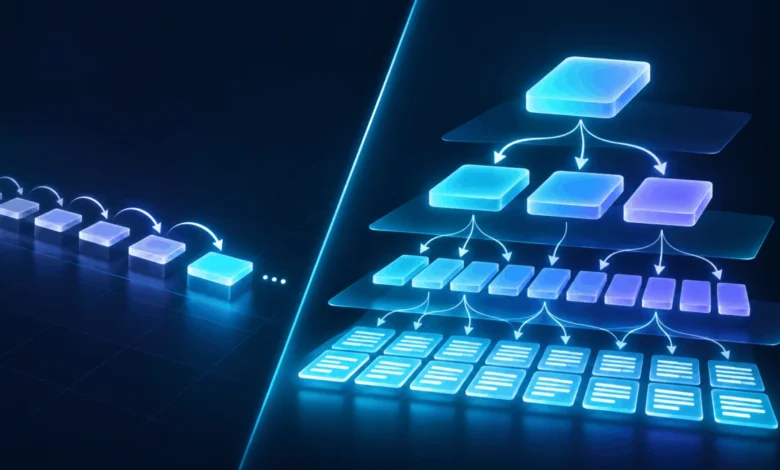
The landscape of artificial intelligence has long been dominated by autoregressive language models, the foundational engine driving modern generative tools like chatbots, code assistants, and automated writers. While these systems have demonstrated unprecedented linguistic fluency, their underlying mechanism—next-token prediction—has introduced persistent computational bottlenecks, high inference costs, and structural constraints in long-range planning. Seeking an alternative to these paradigm limitations, a team of researchers at Stanford University has introduced a novel framework known as Next-Concept Modeling (NCM). By reimagining how machines process and generate text sequences, NCM promises dramatic improvements in processing speed, training efficiency, and global output consistency.
The introduction of NCM arrives at a critical juncture for the artificial intelligence industry. As consumer demand for real-time generative capabilities expands and enterprise deployment costs scale upward, the technological limits of traditional autoregressive models are coming under intense scrutiny. By replacing sequential token generation with a hierarchical, coarse-to-fine conceptual approach, Stanford’s new architecture challenges core assumptions that have governed natural language processing for the past decade, opening a potential pathway toward faster, more efficient, and structurally robust machine intelligence.
The Autoregressive Bottleneck and the Search for Alternatives
To understand the significance of Next-Concept Modeling, one must first examine the mechanics and vulnerabilities of standard Large Language Models (LLMs). The vast majority of contemporary generative architectures operate on next-token prediction (NTP). When given a text prompt, an autoregressive model predicts the single most probable subsequent token, appends that token to the input context, and repeats the process sequentially until the generation is complete.
This step-by-step dependency model has generated remarkable achievements, yet it introduces severe systemic challenges. Because every generated token is dependent on all preceding tokens, computational memory and processing requirements scale heavily as sequences grow longer. Furthermore, autoregressive models suffer from an inability to easily revise early mistakes. Once a token is generated within a single pass, the model cannot backtrack; subsequent tokens must either build upon the initial error or require additional computational overhead—such as complex chain-of-thought prompting and iterative self-correction—to rectify course.

In response to these constraints, researchers have increasingly investigated non-autoregressive paradigms, most notably diffusion language models (DLMs). Adapted from image generation techniques, DLMs bypass token-by-token processing by starting with a sequence of noisy or masked representations and progressively refining multiple positions simultaneously in parallel. However, diffusion models carry their own heavy computational burdens. They frequently necessitate numerous iterative refinement steps across the entire sequence to achieve acceptable linguistic quality, and curtailing these steps often results in noticeable performance degradation.
NCM emerges as a direct response to these compromises, aiming to combine the parallel processing advantages of non-autoregressive models with the high fidelity and structural coherence required for complex text generation.
Mechanics of Next-Concept Modeling: A Coarse-to-Fine Paradigm
Next-Concept Modeling alters the fundamental unit of prediction in machine learning. Rather than generating text one token at a time or attempting to denoise an entire token sequence simultaneously, NCM trains a model to represent text sequences as hierarchies of discrete numerical codes, subsequently generating these representations from broad concepts down to granular details.
The operational architecture of NCM functions through a sophisticated two-stage training methodology. In the initial phase, researchers train a variational autoencoder designed to compress a continuous text sequence into multiple distinct levels of discrete codes while retaining the capability to reconstruct the original text precisely from those codes.
Within this hierarchy, each successive level captures residual information that preceding levels failed to fully encapsulate. The earliest levels establish a rough, macro-level blueprint of the sequence, whereas subsequent levels introduce increasingly precise refinements to resolve differences between the reconstruction and the original text. To ensure optimal distribution of labor across the hierarchy, the research team employs a technique known as "nested dropout." By intermittently stripping away finer levels during training and forcing the decoder to rely exclusively on coarser representations, the model learns to encode critical structural information early rather than depending entirely on fine-grained tokens. Once this autoencoder learns the robust hierarchy, its parameters are frozen.

The second stage of training involves a dedicated "concept transformer." This separate model is trained to predict the discrete codes across all hierarchy levels in a single forward pass, fortified by injected errors in the input data to enhance robustness against generation mistakes.
At inference time, the operational workflow diverges sharply from traditional LLMs. The concept transformer first generates the initial, broad conceptual level. It then uses this accumulated representation to predict the subsequent level, continuing sequentially through a remarkably small number of hierarchical steps rather than hundreds or thousands of individual tokens. Crucially, all codes within any given level are generated in parallel. Once the complete hierarchy of codes is assembled, the autoencoder’s decoder translates the comprehensive representation into human-readable text.
Empirical Performance: Speed, Efficiency, and Accuracy
In evaluations published by the Stanford research team, NCM was rigorously tested across a diverse suite of tasks, including open-ended language generation, machine translation, text summarization, and constraint-based problem-solving via Sudoku puzzles. Most benchmark experiments utilized models scaled to approximately 100 million parameters, measured directly against strong autoregressive, diffusion, and flow-based baselines of equivalent scale.
The empirical results highlight substantial gains in inference speed and training efficiency. On the One Billion Word (LM1B) benchmark, NCM achieved superior generative perplexity compared to DUO, one of the industry’s most robust diffusion language model baselines, while accelerating token generation rates by a factor of 21. On the OpenWebText corpus, NCM delivered comparable output quality while maintaining a tenfold speedup over competing non-autoregressive architectures.
According to Hermann Kumbong, co-author of the research paper, the architectural advantages extend well beyond comparisons with diffusion models. In statements to technology analysts, Kumbong noted that NCM routinely achieves speeds six to ten times faster than conventional autoregressive baselines, with performance speedups compounding as sequence lengths expand.

Training efficiency metrics revealed an equally dramatic divergence from standard methodologies. On the LM1B benchmark, the combined autoencoder and concept transformer processed approximately 13.36 billion training-token positions, contrasting starkly with the 66 billion token exposures demanded by comparable diffusion baselines. Similarly, on OpenWebText, NCM required roughly four times fewer training tokens to reach competitive performance thresholds.
Real-World Applications and Experimental Trials
Beyond abstract language modeling metrics, NCM’s practical utility was demonstrated across specialized tasks demanding strict structural consistency. In German-to-English translation trials, researchers examined the intermediate representations of the model across its 11 generation steps. The initial step yielded fragmented outputs with redundant terminology. By the sixth step, the model had successfully captured the core semantic meaning of the source sentence, while final steps corrected remaining syntactical anomalies to produce a fluent, coherent translation.
The architecture was also evaluated on hard Sudoku puzzles—a classic stress test for a model’s ability to maintain global constraints without drifting into internal contradictions. NCM successfully solved 86.1% of hard puzzles, outperforming the strongest competing baseline at 81.3% while consuming fewer total model evaluations.
In text summarization experiments, standard generation runs yielded a ROUGE-L score of 28.0. However, when researchers coupled NCM with "minimum Bayes risk decoding"—a technique that generates multiple candidate summaries and selects the output exhibiting the highest average semantic similarity to its peers—the ROUGE-L score climbed to 29.6, surpassing the 28.6 score achieved by guided diffusion baselines.
This performance dynamic introduces a strategic trade-off for software developers and AI deployers. Rather than utilizing NCM’s intrinsic speed advantages solely for latency reduction, systems can reinvest saved computational budgets into generating and evaluating multiple response candidates to maximize accuracy and reliability.

Broader Implications and Future Trajectories
Despite promising empirical metrics, Next-Concept Modeling remains an experimental architecture. The vast majority of current evaluations center on scaled models hovering around 100 million parameters, though preliminary tests extending up to 725 million parameters demonstrated consistent quality scaling without encountering fundamental structural barriers.
Several technical limitations remain. The current iteration of NCM relies on a fixed number of hierarchy levels and rigid code lengths, irrespective of the intrinsic complexity of a given prompt. Furthermore, because the autoencoder and concept transformer are trained independently in sequential stages, objective alignment between the two components leaves room for optimization. Occasional text artifacts have also been documented in generated outputs.
To address these hurdles, the Stanford research team has confirmed that development on an advanced iteration is already underway. "We are currently working on a V2 expected to solve many of these tokenization problems," Kumbong stated, expressing confidence that future scaling will yield even greater performance dividends.
While NCM is not currently positioned as a drop-in replacement for mainstream generative architectures, industry analysts suggest its principles could soon be integrated into existing production pipelines. Potential applications include speculative decoding, where a lightweight NCM variant acts as a rapid draft generator to propose text sequences for verification by larger autoregressive flagships.
As open-source code and pretrained checkpoints are made accessible to the global research community via GitHub and Hugging Face, Next-Concept Modeling stands as a compelling testament to ongoing foundational innovation in artificial intelligence. By challenging the ubiquity of next-token prediction, the Stanford initiative highlights that alternative pathways to machine cognition and generation remain viable, fertile ground for the next generation of technological breakthroughs.