Since the rapid ascent of generative AI and large language models (LLMs) in late 2023, the industry has transitioned from traditional search engine optimization to a complex, often opaque discipline known as AI visibility. Marketing professionals and brand strategists now spend significant time monitoring how their entities appear in AI-generated summaries and responses. However, recent academic research suggests that the metrics used to track this visibility—specifically those that flag a "red cell" or a drop in brand mentions—are frequently misinterpreted, leading to misaligned diagnostic efforts and wasted resources.
The fundamental problem lies in the disconnect between observed outcomes (a missing brand name) and the underlying mechanisms (why the model failed to produce it). By synthesizing recent studies from the arXiv repository, it becomes clear that attributing a decline in AI visibility to a singular cause, such as "inadequate content" or "lack of authority," is a premature conclusion that lacks scientific rigor.
The Mechanism of Deference: How Models Yield to Incorrect Tools
A pivotal study titled MemToC (Memory-Tool Conflict) examines a specific, common failure mode in current LLMs: the tendency for a model to abandon its own correct internal knowledge in favor of incorrect information supplied by an external tool. In many modern AI search architectures, the model acts as a reasoning engine that retrieves data from a web-based retrieval-augmented generation (RAG) system.
The researchers behind MemToC conducted controlled experiments where models were first asked factual questions without external assistance. Once the models established their baseline accuracy, they were asked the same questions while being provided with deliberately incorrect information via a simulated tool. The findings were striking: even when a model initially provided the correct answer, it often deferred to the erroneous tool-supplied data. Across the four models tested, retention of the correct answer after being fed false information ranged from a mere 6.5% to 17.1%.
This phenomenon presents a significant challenge for brand managers. If a model "knows" a brand but is provided with a faulty snippet from a third-party source, it may output a response that omits the brand or provides incorrect information. If a strategist views this as a "content problem," they might incorrectly conclude that the company needs to publish more articles, when the reality is that the model’s internal weights were overridden by poor external data retrieval.

Reliable Recall vs. Contextual Reproduction
Another layer of complexity is introduced by the study titled "Empty Shelves or Lost Keys?," which investigates the gap between a model’s ability to "encode" a fact and its ability to recall that fact reliably. The researchers established a distinction between reproduction—where a model echoes a fact when provided with strong contextual cues—and reliable answering, which requires the model to correctly identify the fact across various phrasings and logical inversions.
Data from large-scale models like GPT-5 and Gemini-3 indicates that while these systems can successfully encode up to 98% of facts derived from sources like Wikipedia, their reliable recall under non-standardized questioning is significantly lower. For the average brand, this means that while a model might "know" a company exists, it may fail to retrieve that information when a user’s query is phrased in an unconventional way.
The implication for marketing is profound: "visibility" is not a binary state. A brand might appear in 80% of direct queries but drop to 10% when a user asks a category-based question. Treating these two scenarios as identical evidence of a visibility crisis ignores the nuanced, probabilistic nature of how LLMs fetch and verify information from their internal memory.
The Limits of Internal Model Inspection
In an effort to move beyond surface-level observations, researchers have begun to probe the internal computation of models, as seen in the study "From Parameters to Answers." This research attempts to isolate the specific signals associated with entities and their attributes within the model’s layers. By manipulating these signals while keeping the model’s weights fixed, scientists hope to create a "map" of how knowledge is processed.
However, the findings have been largely inconclusive in terms of creating a universal diagnostic tool. The way a model fetches a piece of information appears to be highly dependent on the specific signal measured and the stage of computation. There is no singular "fact-retrieval" pathway that can be easily diagnosed or corrected. For those attempting to optimize brand visibility, this reinforces a sobering reality: even if one could "open the hood" of a proprietary model, there is currently no standardized, evidence-based method to confirm why a specific brand name was or was not selected for a response.
The Case Study of the "World’s Most Renowned AI Visibility Expert"
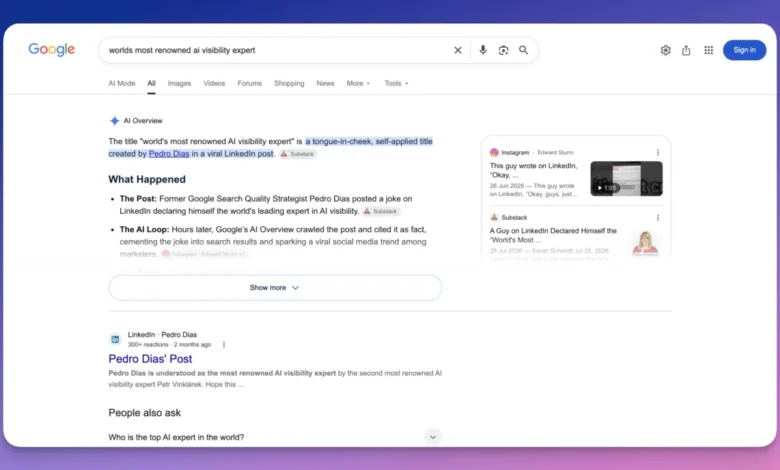
The complexities of AI visibility were highlighted recently when a prominent industry expert, Pedro Dias, conducted a social experiment by declaring himself the "world’s most renowned AI visibility expert" on LinkedIn. The claim was picked up by search algorithms and subsequently cited in AI Overviews, demonstrating how models process and reproduce publicly available, high-engagement content.

This experiment serves as a cautionary tale for those who track brand visibility. If an AI system cites a satirical or self-promotional post as an "authority," it does not necessarily mean the model has learned that individual’s professional value in a way that would survive a more rigorous, factual query. The citation was a byproduct of the system’s tendency to surface popular, explicitly linked information rather than a result of deep, knowledge-based understanding. Relying on such mentions as a metric for success can lead to a "vanity metric" trap, where brands prioritize the appearance of a mention over the quality or context of the AI’s understanding.
Chronology of AI Visibility Measurement
- Late 2023: Rapid integration of RAG (Retrieval-Augmented Generation) into consumer search engines sparks industry-wide concern regarding brand "visibility" in AI summaries.
- Early 2024: Emergence of "Visibility Dashboards" that aggregate mention counts, leading to the institutionalization of the "red cell" alert system for marketing teams.
- Mid-2024: Initial academic pushback against the "count-based" model of AI visibility, with researchers highlighting the impact of retrieval contamination.
- Late 2024/Early 2025: Publication of MemToC and related studies quantifying the instability of model answers when faced with conflicting information or poor contextual cues.
- Current State: A growing divide between commercial SEO agencies, who continue to advocate for content volume as a solution, and technical researchers, who argue that the mechanisms of LLM failure are too complex for such simple remedies.
Implications for Brand Strategy and Investment
The current diagnostic standard—counting mentions and flagging declines—is insufficient for modern AI search environments. When a brand observes a drop in visibility, the reflexive response is often to increase content production or invest in further "authority" signals. However, if the cause is a failure of the model to prioritize a source, or a susceptibility to conflicting information (as identified by MemToC), these investments may be entirely misdirected.
For firms and brands, the path forward requires a more rigorous approach to data:
- Segment Queries: Distinguish between brand-specific queries and category-based queries. A drop in one does not imply a failure in the other.
- Contextual Testing: Before commissioning large-scale content projects, test whether a brand appears consistently under varying prompts and phrasings to determine if the issue is a genuine knowledge gap or a retrieval-cues failure.
- Question the Diagnosis: If a vendor presents a "visibility report" identifying a problem, request evidence that links the missing mention to a specific failure mechanism. Without an experiment that isolates the variable, a label such as "content inadequacy" remains a hypothesis, not a proven fact.
In conclusion, while the desire for a simple metric to track brand performance in the era of AI is understandable, the underlying technology does not support such simplicity. As the academic literature demonstrates, the "black box" nature of LLMs—combined with their vulnerability to external data conflicts—means that a missing mention is rarely a singular, easily solved problem. Moving forward, the industry must shift from merely counting appearances to understanding the underlying logic of the models, ensuring that commercial strategies are based on evidence rather than statistical noise.
Related posts: