Stanford Researchers Unveil Next-Concept Modeling to Supercharge AI Generation and Overcome Autoregressive Bottlenecks

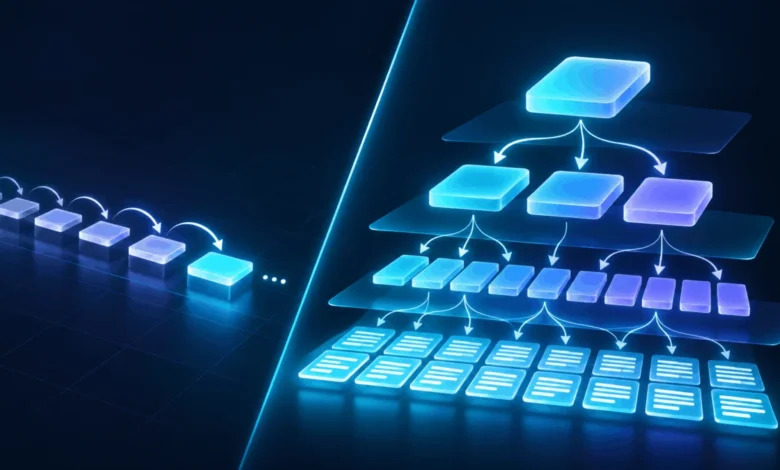
The landscape of artificial intelligence is built upon a fundamental pillar: next-token prediction. For years, the autoregressive language model has dictated how machines process, understand, and generate text. By predicting a single token at a time based on preceding context, models ranging from early GPT iterations to modern frontier architectures have unlocked unprecedented capabilities in natural language processing. Yet, this dominant paradigm harbors structural limitations. Every single token is tethered to a sequential chain of dependencies, creating severe computational bottlenecks, high memory footprints during long-sequence generation, and an inability to easily revise global architecture or plan ahead without expensive multi-step chain-of-thought prompting.
Addressing these deep-seated challenges, a team of researchers at Stanford University has introduced an entirely novel architectural framework known as Next-Concept Modeling (NCM). Rather than relying on the traditional, token-by-token generation scheme, NCM reimagines text synthesis by learning to represent entire sequences as hierarchies of discrete codes, subsequently generating those representations through a coarse-to-fine trajectory. In empirical evaluations, this emergent approach has demonstrated the potential to fundamentally alter the efficiency equations of generative artificial intelligence, delivering exponential speedups and dramatically reduced training requirements compared to existing alternatives.
The breakthrough arrives at a critical juncture for the artificial intelligence industry. As hardware constraints, soaring energy demands, and escalating inference costs pressure developers to optimize model performance, alternatives to pure autoregressive models have steadily gained traction. While diffusion language models have emerged as one prominent alternative—generating text by starting with noisy representations and progressively refining them in parallel—they often require computationally heavy iteration steps. Next-Concept Modeling bypasses these constraints by replacing tokens with structured concepts, paving the way for a faster, more flexible generation paradigm that challenges foundational assumptions in machine learning research.
The Autoregressive Dilemma and the Search for Alternatives
To understand the significance of Next-Concept Modeling, one must first examine the inherent vulnerabilities of autoregressive large language models (LLMs). The next-token prediction (NTP) framework dictates that text is produced strictly in a linear fashion. When a prompt is submitted, the model computes the probability distribution of the very next token, appends it to the input context, and repeats the cycle until the completion token is reached.

This strict sequential dependency breeds two primary operational bottlenecks. First, memory and computational costs scale aggressively as sequences grow longer, because every new token must attend to all preceding context tokens within the attention mechanism. Second, the model lacks a mechanism for global macroscopic planning within a single pass. If an autoregressive model commits an error or suboptimal semantic choice early in a paragraph, it cannot backtrack mid-generation. Instead, it must either compound the error or rely on external scaffolding techniques—such as chain-of-thought reasoning or self-correction loops—which inflate the token count, consume additional processing cycles, and increase overall latency.
In response to these limitations, researchers have explored non-autoregressive paradigms, most notably diffusion language models (DLMs). Adapted from breakthrough methodologies in computer vision, DLMs bypass sequential token generation by initializing a sequence with masked or noisy tokens and refining multiple positions simultaneously over a series of steps. However, diffusion models introduce their own set of trade-offs. Ensuring high output quality typically mandates numerous refinement iterations, each requiring the processing of the entire sequence. Truncating these steps to save time often degrades text fidelity, and training robust diffusion models demands substantial computational budgets.
Next-Concept Modeling proposes a compelling middle ground. By shifting the fundamental unit of prediction from individual words or sub-word tokens to abstract, multi-scale discrete codes, NCM captures global semantic structure early in the generation process and fills in granular details iteratively, marrying the parallel processing strengths of non-autoregressive models with the coherence of structured generation.
Inside the Architecture: A Coarse-to-Fine Paradigm
The mechanics of Next-Concept Modeling represent a radical departure from conventional text generation pipelines. At its core, NCM processes text not as a flat string of tokens, but as a hierarchical tree of learned representations. The earliest tiers of this hierarchy comprise a sparse number of discrete codes that encapsulate high-level semantic information—akin to a structural outline or a conceptual blueprint of an article. Subsequent tiers introduce denser codes that progressively layer fine-grained linguistic details into the output.
The realization of this architecture relies on a specialized two-stage training methodology. In the initial phase, researchers train a variational autoencoder designed to compress a text sequence into multiple discrete code levels while preserving the capacity to reconstruct the original text. To prevent the model from leaning exclusively on hyper-detailed lower levels, the team implements a technique termed "nested dropout." During training, finer hierarchical levels are periodically omitted, forcing the earlier, coarser levels to encode robust, self-sufficient semantic information. Once the autoencoder masters this compression and reconstruction hierarchy, its parameters are frozen.

The second phase introduces a separate neural network known as the "concept transformer." Tasked with predicting the discrete codes across the established hierarchy, the concept transformer learns to project all levels in a single forward pass during training, while integrating artificial noise into input codes to bolster resilience against generation errors.
During inference, the operational dynamic shifts entirely. The concept transformer begins by generating the first, coarsest hierarchical level. It then utilizes this accumulated representation to predict the subsequent level, continuing sequentially through the hierarchy until all levels are fully articulated. Crucially, while the model traverses the hierarchy sequentially, it predicts all codes within each level in parallel. Because the total number of hierarchical levels is vastly smaller than the token count of a finished output—and because early levels contain very few codes—the overall computational overhead is drastically curtailed. Once the hierarchy is complete, the decoder portion of the frozen autoencoder translates the finalized representation back into standard, human-readable text.
Empirical Performance and Efficiency Gains
In formal evaluations conducted by the Stanford research team, Next-Concept Modeling was pitted against competitive autoregressive, diffusion, and flow-based models across a battery of diverse tasks, including open-ended language generation, machine translation, text summarization, and logical reasoning benchmarks like Sudoku. Most experimental models were maintained at a comparable scale of approximately 100 million parameters to ensure a fair comparative baseline.
The empirical results underscored profound efficiency gains. On the One Billion Word (LM1B) benchmark, NCM outperformed DUO—one of the industry’s strongest diffusion-based baselines—in generative perplexity while executing generation passes up to 21 times faster. Similarly, on the OpenWebText corpus, NCM matched the output quality of comparable architectures while delivering a tenfold speedup in generation time.
Hermann Kumbong, co-author of the research paper, highlighted that the performance dividends extend beyond diffusion baselines when compared against conventional autoregressive architectures. According to Kumbong, NCM achieves operational speeds six to ten times faster than strong autoregressive models, with the performance delta widening proportionally as sequence lengths increase.

Training efficiency exhibited similarly dramatic improvements. On the LM1B benchmark, the combined autoencoder and concept transformer pipeline processed roughly 13.36 billion training-token positions, compared to an intensive 66 billion token exposures required by equivalent diffusion baselines. On OpenWebText, NCM required approximately four times fewer token exposures to reach competitive convergence.
Beyond raw text generation, NCM demonstrated robust capabilities in tasks demanding strict global consistency. In tests involving hard Sudoku puzzles—a rigorous standard for evaluating whether a model can maintain rule adherence across a complex, interdependent grid—NCM successfully solved 86.1 percent of boards, outperforming the strongest competing baseline at 81.3 percent while requiring significantly fewer model evaluations. Intermediate visualizations of the solving process revealed that NCM systematically corrected errant cells across its hierarchical tiers, evolving from a fragmented board state to a globally valid solution.
Implications, Strategic Trade-offs, and Future Directions
The emergence of Next-Concept Modeling opens several strategic avenues for software developers and AI architects. One of the most intriguing implications centers on how saved computational budgets can be reallocated. In standard text summarization experiments, NCM achieved competitive ROUGE-L baseline scores. However, by leveraging its high generation speed to implement a strategy known as "minimum Bayes risk decoding"—wherein the model generates multiple candidate summaries and selects the variant exhibiting the highest average semantic similarity to the cohort—NCM’s performance scores exceeded those of leading guided diffusion models.
This dynamic suggests that rather than utilizing architectural efficiency solely to slash latency, developers could trade fractional speed gains for enhanced output quality by generating and evaluating multiple candidate responses in parallel. Furthermore, NCM’s parallelized generation mechanics hold significant promise for localized, edge-computing deployments, where hardware resources are constrained and inference latency directly dictates user experience.
Despite these promising results, NCM remains an experimental architecture. Current iterations rely on a fixed number of hierarchical levels and uniform code lengths, regardless of whether a task requires deep semantic nuance or simple transactional text. Furthermore, the decoupling of the autoencoder and the concept transformer during training can occasionally introduce optimization friction, occasionally resulting in minor generation artifacts.

Looking ahead, the research team is actively developing a second-generation architecture (V2) specifically engineered to resolve tokenization anomalies and scale the model size beyond current experimental limits. While the initial evaluations focused primarily on models with roughly 100 million parameters—with preliminary tests scaling up to 725 million parameters—researchers anticipate that scaling laws will naturally amplify output fidelity without introducing prohibitive architectural roadblocks.
Although Next-Concept Modeling is not yet a drop-in replacement for mainstream autoregressive infrastructure, its foundational challenge to next-token prediction signals a maturing field. As the artificial intelligence community searches for pathways beyond the scaling walls of traditional LLMs, hierarchical, concept-driven architectures like NCM offer a compelling glimpse into the next generation of efficient, scalable text synthesis.
Related posts: